Every cipher described so far was judged by whether anyone had managed to break it. The Vigenère cipher was considered unbreakable for three centuries because nobody had published an attack, and Enigma was considered secure because its designers could not think of one. There was no definition of security and no way to measure how far a cipher fell short of it. Two designs could be compared only by waiting to see which one was broken first.
Claude Shannon, a mathematician at Bell Labs, the research arm of AT&T (the American telephone monopoly back then), changed that. During World War II he worked on the encryption of voice traffic between Roosevelt and Churchill. In 1945 he wrote a classified report, A Mathematical Theory of Cryptography, that applied a new idea of his to ciphers. That idea, published in 1948 as A Mathematical Theory of Communication, founded the field of information theory. The cryptographic report was declassified and published in 1949 as Communication Theory of Secrecy Systems. It defined what a perfect cipher would be, proved that one existed, showed what it would cost, and named the two properties every practical cipher has needed since.
Entropy
Shannon’s starting point was that information can be measured. The measure is called entropy, and it quantifies how uncertain we are about an outcome before we observe it. A fair coin is uncertain. A coin that lands heads 99 times out of 100 is barely uncertain at all, and being told it landed heads tells us almost nothing we did not already know.
For a random variable \(X\) with possible outcomes \(x_1, \ldots, x_n\), each occurring with probability \(p(x_i)\), the entropy is:
\[H(X) = -\sum_{i=1}^{n} p(x_i) \log_{2} p(x_i)\]
The formula is simpler than it appears:
-
The term \(-\log_2 p(x_i)\) is the amount of surprise in outcome \(x_i\), measured in bits. An outcome with probability \(1/2\) has one bit of surprise, an outcome with probability \(1/8\) has three bits, and an outcome that was certain has none.
-
The formula multiplies each outcome’s surprise by how often it occurs and adds the results, so entropy is the average surprise per outcome.
-
The minus sign is there because the logarithm of a probability is negative.
A fair coin has an entropy of 1 bit: two equally likely outcomes, one bit to identify the result. A string of \(n\) bits in which every pattern is equally likely has an entropy of exactly \(n\) bits. This is the maximum entropy for \(n\) bits, and it is what a cryptographic key should look like.
One point about the definition is often misunderstood. Entropy is a property of a probability distribution, not of one particular string. A 128-bit value chosen uniformly at random has 128 bits of entropy because every one of its \(2^{128}\) possible values is equally likely. A 128-character password taken from a famous quotation is longer and looks just as arbitrary to someone who does not recognize it, but it has very little entropy, because an attacker who guesses quotations will find it quickly.
The Entropy of English
If each of the 26 letters appeared equally often, English text would have an entropy of \(\log_2 26 \approx 4.7\) bits per letter (four bits would give us 16 equally likely values, which is too small; five bits give us 32 possible values, which is a little bit more than we need). Counting the actual letter frequencies brings that down to about 4.1 bits. Counting pairs and triples of letters brings it down further, because a Q is almost always followed by a U and a T is often followed by an H. Shannon measured the actual figure in 1951 by having people guess a text one letter at a time, and found that English has only about one bit of information per letter.
The remaining three-quarters or so of each letter is redundancy. The letters are there, but a reader could have predicted them. Redundancy is why a crossword can be solved from a few crossings and why a text message with the vowels removed is still readable. It is also what frequency analysis feeds on. A monoalphabetic substitution relabels the letters and leaves the redundancy exactly where it was, so an analyst with enough ciphertext can reconstruct the key from the statistics alone.
The conclusion for cipher design is a direct outcome of this observation. Ciphertext must carry the maximum entropy its length allows. Anything less is redundancy that an analyst can measure.
Perfect Secrecy
Shannon defined what it would mean for a cipher to leave the analyst nothing at all. A cipher has perfect secrecy if the ciphertext reveals no information whatsoever about the plaintext. Formally, for every possible plaintext \(p\) and every ciphertext \(c\):
\[\Pr[P = p \mid C = c] = \Pr[P = p]\]
Reading the notation:
-
\(P\) is the plaintext that was sent and \(C\) is the ciphertext that was intercepted. Both are random variables, since the adversary does not know which message was chosen or which key was used.
-
\(\Pr[P = p]\) is the probability, before seeing any ciphertext, that the message is some particular \(p\). This is the adversary’s prior knowledge: some messages are more likely than others.
-
\(\Pr[P = p \mid C = c]\) is the probability that the message is \(p\) given that the ciphertext turned out to be \(c\). The vertical bar is read “given.”
The equation says that seeing the ciphertext does not change the probability of any possible message. Suppose an adversary believes there is a 70% chance that the message is “ATTACK” and a 30% chance that it is “DEFEND.” With perfect secrecy, those probabilities remain 70% and 30% after the ciphertext is intercepted. The adversary can guess, but seeing the ciphertext does not help.
No amount of computing power changes this. The ciphertext contains no information that would allow the adversary to distinguish among the possible plaintexts.
Perfect secrecy only applies to message contents. It does not hide who is communicating, when, or how often, so traffic analysis can still be useful. Message length needs some care: perfect secrecy is usually defined over messages of a fixed length. A cipher that reveals length cannot satisfy the equation across messages of different lengths, because knowing the length rules out some possible plaintexts.
The One-Time Pad
The system Shannon proved perfect predates his work by decades. In 1917, Gilbert Vernam, an engineer at AT&T, built a device that encrypted teleprinter traffic by representing each character as five bits on punched paper tape. The machine read a second tape of key characters alongside the message tape and combined them with what we would now call XOR. The same operation with the same key tape decrypted the message at the far end. It was the first cipher machine that worked on bits.
The key tapes were the problem. A key tape had to be as long as the message. To reduce the amount of tape needed, AT&T’s engineers looped it, or combined two short tapes of different lengths to produce a long but periodic key. Joseph Mauborgne, a U.S. Army Signal Corps officer, showed that any key tape that repeated could be attacked, and insisted that the key (1) be truly random, (2) be as long as the message, and (3) never be used twice.
Vernam’s machine with Mauborgne’s rule is the one-time pad, named for the pads of paper on which the key material was later printed for manual use. Shannon’s contribution, nearly thirty years later, was to prove that those three conditions guarantee perfect secrecy and that a key with less entropy than the message cannot.
The one-time pad can encrypt letters just like the Vigenère cipher, but it uses a truly random key that is at least as long as the message and is never reused.
On bits, which is how machines use the pad, the one-time pad relies on the exclusive-or operation, written \(\oplus\) and called XOR. The result of an XOR is 1 when the bits differ and 0 when they are the same.
The one-time pad works as follows:
-
The plaintext \(P\) is a string of \(n\) bits.
-
The key \(K\) is a string of \(n\) bits chosen uniformly at random.
-
Encryption is \(C = P \oplus K\), the bitwise exclusive-or.
-
Decryption is \(P = C \oplus K\), since XORing with the same key twice cancels it out.
For example, with an 8-bit message:
Plaintext:  10110010
Key:        01101100   (random)
Ciphertext: 11011110

Decrypt:    11011110 XOR 01101100 = 10110010
Two properties of XOR are needed for the proof. XORing with the same string twice restores the original, since \(x \oplus k \oplus k = x\), which is why decryption works. And if \(k\) is a random bit, then \(x \oplus k\) is a random bit whatever \(x\) was, which is why the ciphertext reveals nothing.
The idea behind the proof is as follows. Take any intercepted ciphertext and any candidate plaintext of the same length, say ATTACK. There is exactly one key that would have turned that plaintext into that ciphertext, and there is also exactly one key that would have turned DEFEND into it. Since every key was equally likely to have been chosen, the ciphertext gives the adversary no reason to prefer one candidate over the other.
The Conditions for Perfect Secrecy
Each of the three requirements is essential for perfect secrecy to hold:
-
The key must be truly random and chosen independently of the message. If some keys are more likely than others, some plaintexts become more likely than others once the ciphertext is seen, and the equality in the definition fails. If the key depends on the message in any way, then the ciphertext depends on the message in the same way.
-
The key must be at least as long as the message. If it is shorter, there are fewer keys than possible plaintexts, so some plaintexts cannot have produced the observed ciphertext, and the adversary has learned something.
-
The key must never be reused. This is the condition that is most often violated, and the consequences are immediate.
Suppose two messages \(P_1\) and \(P_2\) are encrypted with the same key \(K\):
\[C_1 = P_1 \oplus K, \qquad C_2 = P_2 \oplus K\]
An adversary who intercepts both can XOR them together:
\[C_1 \oplus C_2 = P_1 \oplus K \oplus P_2 \oplus K = P_1 \oplus P_2\]
The key cancels out. What remains is the XOR of two plaintexts, and because natural language is redundant, that is usually enough. The adversary guesses a common word in one message, XORs it into the combined stream, and checks whether the result is readable text from the other message. Readable text confirms the guess, and nonsense rejects that guess. Each correct guess reveals a fragment of both messages, and with a few hundred characters of overlap, both can be recovered.
The best-known case of reuse was Soviet diplomatic traffic of the 1940s. Under wartime pressure, the printing plant that produced the pads issued thousands of duplicate pages, and American analysts spent the following decades reading the messages they carried. The appendix describes the project, which was named VENONA.
The Cost of the One-Time Pad
A one-time pad turns the problem of sending a secret message into the problem of sending a secret key of the same length, which is no easier. The key has to be generated from a true random source, delivered to the receiver via a secure channel, stored safely, kept in sync, and destroyed after use. Every byte of traffic consumes a byte of key, and a channel secure enough to carry that much key could usually have carried the data instead.
Shannon proved that this cost cannot be avoided. Perfect secrecy requires the key to have at least as much entropy as the message. No cipher can provide perfect secrecy for an unlimited amount of traffic from a fixed short key.
For a small amount of extremely valuable traffic, that cost and effort can be justified. The direct line between Washington and Moscow, installed in 1963, used one-time tapes exchanged by courier. But no bank, army, or web browser can distribute keys that way at scale. The one-time pad demonstrates what is possible, but it is not used for ordinary traffic.
Computational Security
Since perfect secrecy is unaffordable, every practical cipher settles for something weaker. Instead of an adversary with unlimited power, the design assumes a bounded adversary, one limited by time, computing power, money, and the amount of ciphertext available. A cipher has computational security if breaking it is infeasible for such an adversary, even though it may be possible in principle. The ciphertext contains enough information to determine the plaintext, but extracting it would take longer than the adversary can wait.
The claim rests on two requirements:
-
The key must be long enough that trying every key is infeasible.
-
The cipher must have no shortcut, meaning no attack based on its structure that does substantially better than trying every key.
The first requirement is arithmetic. An \(n\)-bit key chosen at random takes \(2^n\) trials to search in the worst case and \(2^{n-1}\) on average. Each added bit doubles the work, so a 128-bit key has \(2^{72}\) times as many possibilities as the 56-bit key of the DES cipher described later.
The second requirement can never be proved. New analysis could find a shortcut at any time, and faster hardware steadily lowers the cost of known attacks. Designers therefore publish their ciphers for analysis, choose key sizes with a safety margin, and try to build systems so that an algorithm can be replaced when the assumptions underlying it no longer hold.
A common way to define secure encryption is through computational indistinguishability: an attacker who chooses two messages of the same length and receives an encryption of one should be unable to tell, with odds significantly better than guessing, which one was encrypted, given realistic limits on computing power and time. Patterns or statistical biases that help the attacker make that choice reveal a weakness in the encryption.
Attack Models
What an adversary can do depends on what the adversary has, and cryptographers name the cases:
-
In a ciphertext-only attack, the adversary has intercepted ciphertext and nothing else. Frequency analysis of a monoalphabetic cipher is an example. This is the weakest adversary, and a cipher that cannot resist it is useless. Against a modern cipher, a purely ciphertext-only break is essentially unheard of.
-
In a known-plaintext attack, the adversary also has some plaintext and its corresponding ciphertext. The cribs used against Enigma are known plaintext. The analysts knew the weather report began with WETTER and used that to recover the day’s settings.
-
In a chosen-plaintext attack, the adversary can get messages of their own choosing encrypted and observe the results. When the Royal Air Force mined a stretch of sea in 1941 so that the German navy would encrypt its coordinates, Bletchley Park was mounting a chosen-plaintext attack. Any system that encrypts data supplied by outsiders, which includes every web server, faces this adversary.
-
In a chosen-ciphertext attack, the adversary can also submit ciphertexts of their own construction for decryption and learn something from the result, even if only whether the decryption succeeded. We will cover attacks of this kind in detail later, when we discuss message integrity.
Modern ciphers are designed to resist chosen-plaintext attacks at a minimum, and systems are expected to resist chosen-ciphertext attacks as well.
Confusion and Diffusion
Indistinguishability says what ciphertext must look like. It does not say how to build a cipher that produces it, and Shannon’s paper addressed that too. He identified two properties that a strong cipher must have, and he gave them names that are still in use:
Confusion makes the relationship between the key and the ciphertext as complicated as possible. Each bit of ciphertext should depend on the key in a way that cannot be described by a short equation. An adversary who collects many plaintext and ciphertext pairs should not be able to solve for the key. Modern ciphers get confusion from substitution boxes, or S-boxes. An S-box is a small lookup table that maps a few input bits to a few output bits according to a deliberately irregular, nonlinear rule.
Diffusion spreads the influence of each plaintext bit across many ciphertext bits, so that the statistical structure of the plaintext is dissipated through the whole ciphertext rather than showing up locally. Modern ciphers get diffusion from permutations and from linear mixing operations that move bits or bytes to new positions and combine them with their neighbors.
Good diffusion produces the avalanche effect: changing a single bit of the plaintext or the key should change about half the bits of the ciphertext, and which half should be unpredictable. Two plaintexts that differ in one character should produce ciphertexts that look completely unrelated. Avalanche is a useful test, and a cipher that fails it is broken, but passing it proves nothing. A weak design can scatter every input change throughout the output while still containing a mathematical shortcut.
Neither property is enough on its own. A cipher with confusion but no diffusion is a collection of independent small substitutions, and each can be attacked separately, which is what happened to Playfair. A cipher with diffusion but no confusion is a linear function, and a linear function can be solved with a few known plaintexts, whatever its size. Each plaintext and ciphertext pair gives a linear equation in the key bits, and as many equations as there are key bits can be solved by Gaussian elimination.
Shannon’s proposal was to alternate them: apply a substitution step, then a mixing step, and repeat the pair over and over, mixing in key material each time. Each repetition is a round. A single round is weak. After enough rounds, every bit of the output depends on every bit of the input and every bit of the key in a way that no known analysis can separate. This is the design of nearly every block cipher in use today. ADFGVX, with its one substitution and one transposition, was this design with a single round.
Randomness
Both perfect secrecy and computational security rest on randomness. A one-time pad needs a random key. A modern cipher needs a random key and usually a random per-message value as well. Confusion and diffusion describe what a cipher does with a key. They cannot protect a key that the adversary can guess. An adversary who can predict the random values does not need to attack the cipher, and the failures at the end of this section show how often that happens.
The difficulty is that a computer is a deterministic machine. Running an algorithm, however elaborate, creates no new uncertainty, because anyone who knows the algorithm and its starting point can run it too. Unpredictability has to come from outside the program. Every operating system collects a small amount of it from physical events and expands it with an algorithm.
Random and Pseudorandom
Three kinds of sequences go by the name random:
-
True random bits come from a physical process that cannot be predicted, such as electronic noise in a circuit or the arrival times of keystrokes and network packets. A source of such bits is an entropy source. These sources are slow and sometimes biased, and they have to be measured and cleaned up before use.
-
Pseudorandom bits come from a deterministic algorithm, a pseudorandom number generator (PRNG), that starts from a short seed and expands it into a long sequence. The sequence passes statistical tests, but anyone who knows the seed can regenerate all of it. The generators in most programming language libraries are of this kind, designed for simulations and games, not for secrets.
-
A cryptographically secure pseudorandom number generator (CSPRNG) is a PRNG whose output cannot be distinguished from true randomness by anyone who does not know the seed, and whose future output cannot be predicted from its past output. A CSPRNG seeded from a few hundred bits of true randomness can safely produce as many bits as any application needs.
Operating systems provide the CSPRNG, and application code should use it rather than construct its own. Linux collects entropy from hardware timing and device events into a kernel pool and offers it through the getrandom() system call and /dev/urandom. Windows and Apple’s systems provide equivalent calls.1 Modern processors add a hardware noise source, such as Intel’s RDRAND instruction, and the kernel mixes all of its sources together so that a weakness in one does not compromise the pool.
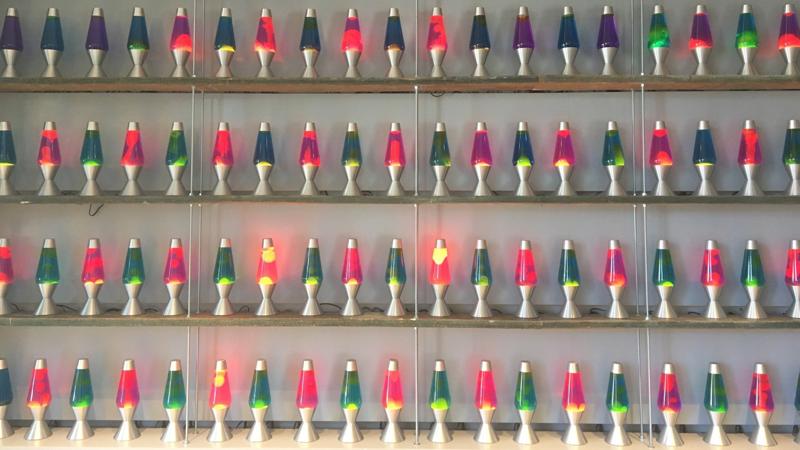
Cloudflare photographs a wall of about one hundred lava lamps in the lobby of its San Francisco office and mixes the image data into the entropy that seeds its servers. The system would work without the lamps; they are a visible demonstration that a computer needs input from the physical world to produce unpredictable values. The appendix describes this and other physical sources.
Failures of Random Number Generation
Poor random number generation has broken more real systems than any weakness in a cipher. A freshly booted device may not have collected enough entropy yet. A virtual machine cloned from an image starts with the same state as every other clone. Embedded devices have few sources of noise and generate their keys at first boot, when they have the least. Three failures illustrate this:
-
Debian OpenSSL (2008). In 2006, a Debian developer commented out two lines in the OpenSSL library to silence a warning from a memory checker. The lines were what fed entropy into the generator. For the next two years, every key generated on a Debian or Ubuntu system was drawn from a set of only 32,767 possibilities per key size, determined entirely by the process ID. All of those keys had to be found and replaced.
-
Sony PlayStation 3 (2010). Sony signed its software with a digital signature algorithm that requires a fresh random number for every signature. Sony’s code used the same number every time. A group of hobbyists recovered Sony’s private signing key from two signatures and presented it at a conference in Berlin.
-
Internet-facing RSA certificates (2019). An RSA public key, which we will cover later, is built from two large secret primes, and two keys that share a prime can both be broken by anyone who notices. Researchers collected 75 million RSA public keys from devices on the Internet and found about 435,000 certificates whose keys shared a prime with another, which happens when the generators that produced them had too little entropy. They recovered nearly 250,000 distinct private keys, mostly from routers, cameras, and other embedded devices, for less than $3,000 of cloud computing time.
In every case, the cipher or signature algorithm was sound, the random number supplied to it was predictable, and the adversary attacked the number.
Next: Part 4: Modern Symmetric Ciphers
-
BCryptGenRandom()on Windows andSecRandomCopyBytes()on macOS and iOS. ↩